A-01 · Protocol
Bell state
Two qubits, maximally entangled: only 00 and 11 appear, half each.
Founded in Varna in 2003, Quanterall now works on quantum algorithms, quantum error correction and quantum circuit simulation. What exists: ten quantum circuits you can run on this page, simulated on the Erlang virtual machine, with their source code public; a simulation engine we built over the last two years for the EU research project TechUPGRADE, which we now use for simulations in other fields, quantum computing among them; and an Erlang practice that goes back to 2009.
The name was coined in 2002 at the Joint Institute for Nuclear Research in Dubna. The company was incorporated on 23 March 2003 to pursue it once the technology allowed.
How this was built. Most of the code since 28 October, and the checks around it, were written with an AI coding assistant (Claude, by Anthropic), directed by our team; that is why so much is dated within two days, after a project begun in February 2026. We rely on independent tools rather than on the assistant: the circuits are compared with Qiskit, the stabilizer sampler with Stim, the decoding is PyMatching's, and the scripts and data are published. No independent physicist has reviewed the work yet; that review belongs to the preprint.
QxSim checked against Qiskit: 55 random circuits on 2 to 12 qubits (2,310 gates: H, X, Rx, Ry, Rz, CNOT, CZ, controlled phase, swap), each final state vector compared with Qiskit's — the worst fidelity is 1 − 7 × 10⁻¹⁵, while one angle changed by 0.01 rad shows as 2.5 × 10⁻⁵ (data, tools/beam_runs.exs xval). Circuits with measurement in the middle: every error-correcting code with every single error, before and after correction, and teleportation of random states, rebuilt in Qiskit as dynamic circuits — mid-circuit measurement, reset, corrections conditioned on the measured bits — and run on Aer, 4,000 shots each, each comparison with its own seeds. 8 comparisons have one outcome on both sides: all equal. For the other 61, chi-square tests: the smallest p-value is 0.03 and they spread over the whole range, with more near 1 than a uniform spread would give (the test is conservative on sparse tables; the comparisons are not all independent). Each check is shown to bite: Aer driving Bob's X and Z with the wrong bits, Aer's Steane decoder off by one position, a Qiskit circuit with one angle changed by 0.01 rad — each is caught at once (data, tools/dynamic_xval.py).
| engine | language · where | runs |
|---|---|---|
| QxSim | Elixir · our BEAM service (lib/qx_demo.ex), served by Erlang/Nova | the live circuits and codes on this page; the state-vector benchmark |
| QxStab | Elixir · the same service (lib/qx_stab.ex) | gate-level noise: the threshold study, GHZ on 2,000 qubits, the live noise run; the stabilizer benchmark |
| QxProcesses | Elixir · the same service, plus a second BEAM node | the two process models |
| QxFock | Elixir · the same service (lib/qx_fock.ex) | photons in Fock space: the HOM dip, the KLM NS and CZ gates (and its twin fock.py in the TechUPGRADE engine) |
| QxCV | Elixir · the same service (lib/qx_cv.ex) | one optical mode in continuous variables: GKP readout under shift noise, cat parity under loss, the heralded comb (and its twin cv.py in the TechUPGRADE engine) |
| QxDecode | Elixir · the same service (lib/qx_decode.ex) | our union-find decoder, compared with PyMatching on the study's syndromes |
| our NumPy engine | Python · the simulation engine we built for TechUPGRADE (its quantum module; a copy in this repository's qsim/) | the repetition-code sweeps (each error pattern through the syndrome circuit); the NumPy column of the benchmark |
| Stim, PyMatching, Qiskit | Python · other people's open-source tools, run by our scripts in tools/ | checking our work: Stim samples the same circuits and derives the detector error model; PyMatching decodes; Qiskit gives reference state vectors; Aer is benchmarked |
On 23 March 2026, 23 years to the day after incorporation, Quanterall changed from a distributed-systems engineering firm into a quantum computing research company. The name "Quanter-all" was chosen in 2002 at the Joint Institute for Nuclear Research in Dubna as a statement of intent toward quantum computing.
A research programme begun on 23 March 2026, not a product company. We keep it to what we can show: quantum algorithms and error-correcting codes, implemented and tested in a state-vector simulator in our demo service. Its first public pieces are the circuits and the simulation work above.
We model an entangled pair as two Erlang processes whose states are linked: measuring one fixes what the other will show. This is a classical simulation: a third process holds the shared state centrally and both sides ask it, so the model reproduces the statistics of entanglement, not nonlocality. The demo below measures S live and shows it with its standard error (about ±0.06 over 2000 rounds), against 2 for any classical model and 2√2 ≈ 2.83 in theory. For teaching: it makes visible that the correlation comes from the shared state, not from a message between the two.
We model teleportation as a process that migrates between two BEAM nodes: the state leaves one node and is rebuilt on the other, carried only by a Bell pair shared in advance and two classical bits sent over the network — as in the protocol, where nothing quantum travels after the pair is made. The simulator knows ψ — it draws it at random and checks the result — so the demo shows the protocol's structure, not a physical transmission. For teaching and for prototyping protocols.
Why we publish the speculative work: a lab that only shows finished results is telling you nothing about how it thinks.
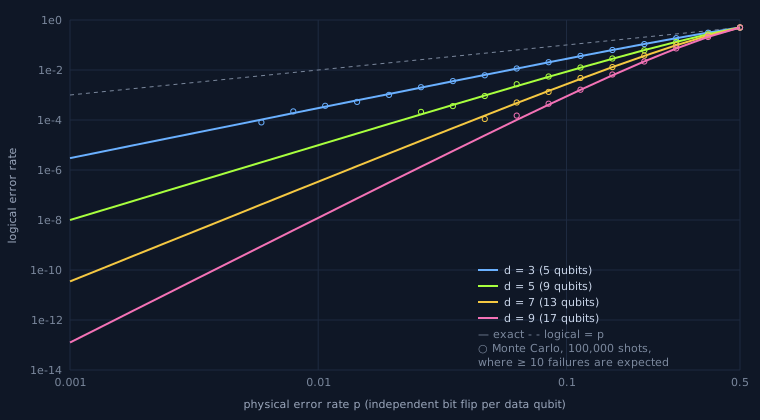
Noise model. A bit-flip repetition code of distance d keeps logical |0⟩ on d data qubits, with d − 1 ancillas measuring neighbouring parities. Each data qubit flips (X) independently with probability p; gates and syndrome measurements are perfect; a minimum-weight decoder picks the correction.
Exact, and what it checks. There are only 2ᵈ error patterns. Each is run once through the syndrome circuit on our NumPy state-vector engine (the TechUPGRADE engine's quantum module; tools/repetition_sweep.py calls it, and computes the closed form beside it), and the logical error rate is the sum of the failing patterns' probabilities. For this noise model a closed form exists — the binomial tail Σk>d/2 C(d,k) pᵏ(1−p)ᵈ⁻ᵏ — and the two agree to 6 × 10⁻¹⁶. That agreement is close to guaranteed: bit flips on |0…0⟩ keep the state a single basis state, so it tests the circuit's logic, not superposition or phase. The test of those is the cross-check against Qiskit below. A Monte Carlo experiment with 100,000 shots per point (seed 20261029) is drawn beside it.
What it does not show. Circuit-level noise — errors in the gates and in the syndrome measurement itself — has no simple formula, and is where real study begins. That, and codes beyond the roughly 20 qubits a state vector allows, need a stabilizer simulator; both are on our list (see Where we are).
Data (CSV, 88 rows) · Chart (SVG) · computed on the simulation engine we built for TechUPGRADE, 29 October 2026; the generator is tools/repetition_sweep.py in the repository
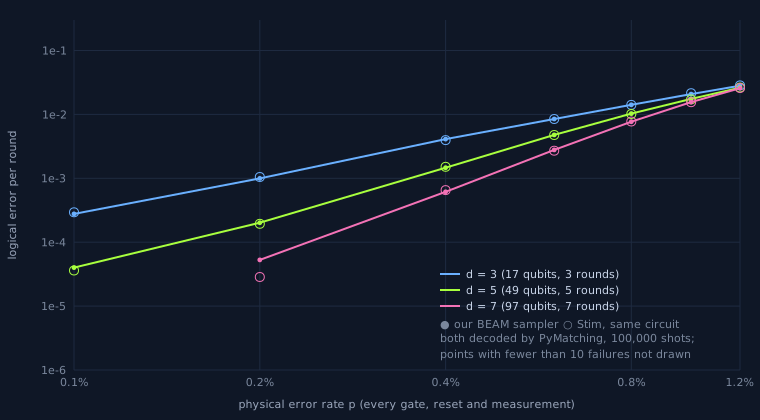
The simulator. QxStab, a stabilizer simulator written in Elixir: a tableau (Aaronson–Gottesman) runs each circuit once without noise for a reference, then a Pauli-frame sampler runs the shots, bit-packed — 1,024 shots in one integer per qubit — in parallel batches, one BEAM process each. It is the method Stim uses, written for the BEAM.
The experiment. Rotated surface codes of distance 3, 5 and 7 (17, 49 and 97 qubits) keep a logical |0⟩ for d rounds of stabilizer measurements. Noise at rate p everywhere: depolarizing after every gate (one- and two-qubit), bit flips after resets and before measurements, depolarizing on the data at each round.
Validation, and what it covers. Each circuit is written out in Stim's format: Stim accepts every detector as deterministic and finds the code distance d for each (our first CNOT order gave only (d+1)/2, a hook-error mistake Stim caught). The detector error model, and so the decoding, comes from Stim; what is compared is the sampling alone. Sampled by Stim and by us, both decoded by PyMatching: the logical error rates agree. Stricter, with exact binomial tests (our count against Stim's, given their sum): every detector's firing rate at all 21 points (3,360 tests, 0.30 % below p = 0.0027 against 0.27 % expected); every detector together with the logical observable, the correlation that sets the logical error rate (3,360 tests, 0.36 %); every pair of detectors for d = 5 at p = 0.6 % (7,140 tests, 0.18 %); and the decoded logical error rates themselves (21 tests, the smallest p-value 0.70 after Bonferroni correction). The detectors are not independent, so these shares are a guide, not a calibrated test. The tests have power: Stim at p = 0.65 % against Stim at 0.6 % is flagged on 97 % of detectors (numbers, tools/stim_exact.py).
What it shows. The curves cross between p = 0.6 % and 0.8 % — three distances and seven error rates bracket the crossing, they do not estimate it (that would need finer steps near it and a finite-size fit). The bracket is in line with published values for this noise model, roughly 0.5 to 1 %: below it, a larger code protects better. The decoder is PyMatching's, not ours.
Data (CSV, 21 points, 100,000 shots each) · Chart (SVG) · tools/beam_runs.exs, tools/stab_study.py · stim 1.16.0, pymatching 2.4.0
| qubits | gates | QxSim (BEAM) | our NumPy engine | Qiskit Aer |
|---|---|---|---|---|
| 8 | 120 | 1.1 (1.0) | 0.6 (0.6) | 3.5 (3.2) |
| 10 | 190 | 4.5 (4.4) | 1.2 (1.2) | 4.7 (4.6) |
| 12 | 276 | 28.1 (28.0) | 2.7 (2.6) | 7.9 (7.5) |
| 14 | 378 | 199 (176) | 8.4 (8.3) | 8.6 (8.3) |
| 16 | 496 | 1,304 (1,137) | 36.3 (36.0) | 78.7 (42.1) |
| 17 | 561 | 2,994 (2,924) | 81.1 (80.8) | 29.1 (27.2) |
| 18 | 630 | 6,394 (5,528) | 196 (192) | 90.5 (69.6) |
| 19 | 703 | 20,542 (13,645) | 585 (575) | 210 (138) |
| 20 | 780 | out of memory | 1,933 (1,867) | 208 (203) |
The circuit: n layers of Rx on every qubit and CNOTs on neighbours, then 1,024 shots. Timed: building the state and sampling, after one warm-up run; Qiskit's transpilation is not timed. QxSim keeps the state as an Erlang tuple of boxed complex numbers, in one process, rebuilt for every gate: fine for teaching circuits, and about 100 times slower than Aer at 19 qubits; at 20 it runs out of its 1 GB container. Our NumPy engine runs with OpenBLAS on one thread: with its default of 20 threads, each one-qubit gate (a 2×2 matrix against 2ⁿ⁻¹ columns, through tensordot) spent its time starting threads — 15 ms per gate at 20 qubits against 3.5 ms on one thread — which made an earlier version of this table jump 15× at 20 qubits. Profiled, not guessed; one thread is also like for like with QxSim, a single process. Aer's times vary a lot from run to run, hence the minimum beside the median.
| circuit | qubits | QxStab, 20 schedulers | Stim, 1 core | Stim, 20 processes | QxStab / Stim ×20 |
|---|---|---|---|---|---|
| repetition d9 | 17 | 14.0 | 14.0 | 1.8 | 8× |
| surface d3 | 17 | 8.5 | 3.2 | 1.1 | 8× |
| surface d5 | 49 | 20.4 | 22.6 | 2.8 | 7× |
| surface d7 | 97 | 124 | 99.0 | 6.4 | 19× |
| surface d9 | 161 | 371 | 193 | 13.6 | 27× |
Timed: for QxStab, the reference tableau and the sampling, batches of 1,024 shots in parallel BEAM processes; for Stim, compiling the sampler and sampling — on one core, and split over 20 worker processes (started before timing). Like for like, on 20 cores, Stim is 8 to 30 times faster. Against one Stim core our sampler is between 2.8 times slower and about even. What the BEAM offers is not speed but a simple way to spread shots over cores and machines, with batches that cannot crash one another — and Stim spreads just as easily.
Data (CSV) · where: one machine, 20 Arm (aarch64) cores; QxSim and QxStab in the quanterall_quantum container (1 GB memory limit, 20 schedulers), Python on the host (OpenBLAS on one thread) · stim 1.16.0, pymatching 2.4.0, qiskit-aer 0.18.2 (statevector) · tools/beam_runs.exs, tools/stab_study.py
What this is. Simulations of schemes from the literature — not photonic hardware. A photon simulator in Fock space, written twice from one conventions file (docs/optics_conventions.md): QxFock in Elixir (this service) and fock.py in the TechUPGRADE engine. Each applies an interferometer two ways (expanding creation operators; permanents by Ryser's formula). On 60 random interferometers of 4–8 modes and 1–4 photons, every output amplitude agrees: the two routes to 1e-15, Python with Perceval (Quandela) to 2e-16, Elixir with Python to 2 × 10⁻¹⁵; one beamsplitter sign flipped shows as 0.61.
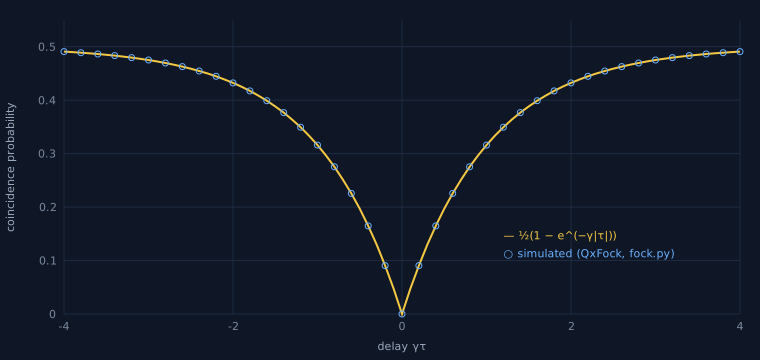
Hong–Ou–Mandel. Two photons meet on a balanced beamsplitter; when they overlap fully they always leave together. With exponential pulses offset by τ (overlap e^(−γ|τ|/2)) the coincidence probability is ½(1 − e^(−γ|τ|)): simulated at 81 delays, it matches to 2e-16 and is exactly 0 at τ = 0.
The KLM gates (Knill, Laflamme, Milburn, Nature 409, 46, 2001). The nonlinear sign gate, from KLM's own 3-mode unitary and from the beamsplitter form (angles 22.5°, 65.5302°, −22.5° and a π phase): on 50 random inputs α₀|0⟩ + α₁|1⟩ + α₂|2⟩ it gives α₀|0⟩ + α₁|1⟩ − α₂|2⟩ with probability 1/4 and fidelity 1 − 10⁻¹⁵. Two of them make a CZ on dual-rail qubits (8 modes, 4 photons): process fidelity 1 − 3 × 10⁻¹⁶, success exactly 1/16.
Checks that bite, and one that did not. The middle angle off by 0.5° lowers the CZ fidelity to 0.9997. Leaving out the π phase was expected to break the gate; it does not — it gives diag(1, −1, −1) per NS gate, and the circuit becomes CZ followed by Z on both qubits, still a CZ up to single-qubit phases. So that is no power check, and we say so.
Fusion (Browne and Rudolph, PRL 95, 010501, 2005). Type-I fusion, simulated photon by photon — polarising beamsplitter, 45° rotation, one polarisation-resolving detector — acts on the two input qubits as (|0⟩⟨00| ± |1⟩⟨11|)/√2 (to 10⁻¹⁶), succeeds with the input's weight on |HH⟩ and |VV⟩ (½ for cluster qubits), and its failures are Z measurements of both. Type II succeeds with probability ½ and projects onto one Bell state, Φ⁺ or Ψ⁺: linear optics tells apart two of the four. On state vectors, fusing the ends of linear clusters of n and m qubits (2–5) gives the cluster of n + m − 1 with fidelity 1 − 2 × 10⁻¹⁶.
Growing a chain. A long linear cluster grows by fusing k-qubit pieces onto its end, each piece itself built from Bell pairs by fusion; on a failure the chain loses its end qubit and the piece its first. Bell pairs used per qubit gained (Monte Carlo, 20 × 20,000 attempts):
| piece, qubits | leftover discarded | leftover reused |
|---|---|---|
| 2 | never | never |
| 3 | 7.98 ± 0.04 | 7.01 ± 0.04 |
| 4 | 9.07 ± 0.04 | 7.01 ± 0.03 |
| 5 | 10.65 ± 0.03 | 7.68 ± 0.02 |
| 6 | 12.48 ± 0.02 | 8.46 ± 0.02 |
Bell pairs alone (k = 2) never grow the chain — success adds one qubit, failure takes one away. Three-qubit pieces cost 8 pairs per qubit, or 7 when the two-qubit leftover of a failure is reused: the review's "2 × 4 − 1 = 7". Its "6.5" we do not find in any strategy we simulated; the best are 7.0, with three- or four-qubit pieces and reuse (data, fusion checks, /quantum/optics/fusion).
Measurement-based computation (on state vectors). One-bit teleportation through a two-node cluster and a rotation along a chain (adaptive angles, Pauli byproducts) reach fidelity 1 on random inputs. The review's four-node example does not hold as drawn: its Fig. 10 chain (CZ₁₂CZ₂₃CZ₃₄) gives a CZ between the teleported input and the fourth qubit — CNOT-class by its local invariants, but needing gates before as well as after; the couplings its Eq. 56 writes (1–2, 2–3, 2–4) do give a CNOT for every outcome and for superposition inputs, with Pauli byproducts when built from CZ gates (data).
Detectors and loss. A detector of efficiency η is a beamsplitter onto an empty mode before an ideal detector: its outcome probabilities match the bucket and number-resolving formulas (the review's Eqs. 80–81) to 4 × 10⁻¹⁶. Through such detectors on the heralds, lost photons make false heralds; with bucket detectors, which cannot tell one photon from two, the gates fail even at η = 1:
| η | NS fidelity, resolving | bucket | CZ fidelity on |++⟩, resolving | bucket | CZ herald rate |
|---|---|---|---|---|---|
| 1.00 | 1.0000 | 0.7216 | 1.0000 | 0.4667 | 0.0625 |
| 0.99 | 0.9941 | 0.7199 | 0.9836 | 0.4639 | 0.0623 |
| 0.95 | 0.9702 | 0.7130 | 0.9210 | 0.4529 | 0.0612 |
| 0.90 | 0.9398 | 0.7045 | 0.8493 | 0.4395 | 0.0596 |
| 0.80 | 0.8796 | 0.6877 | 0.7256 | 0.4139 | 0.0551 |
| 0.50 | 0.7271 | 0.6404 | 0.4714 | 0.3466 | 0.0331 |
And a photon lost from a dual-rail qubit leaves exactly ηρ + (1 − η)|vac⟩⟨vac| (to 2 × 10⁻¹⁶): an erasure, heralded by the missing photon — the error model of our next step, decoding erasures (data, CSV).
Erasure decoding — the part that is ours. A lost photon is a heralded erasure: the qubit is known to hold a random Pauli. Our union-find decoder, QxDecode, takes erased edges as already grown and weightless in the peeling tree — for pure erasure the peeling decoder of Delfosse and Zémor, which is maximum-likelihood. At code capacity (the rotated surface code, perfect syndrome, 20,000 shots a point, PyMatching with the erased edges at weight 0 on the same shots beside it), pure erasure crosses at 50 % for d = 3 to 9, the percolation threshold, and the two decoders agree:
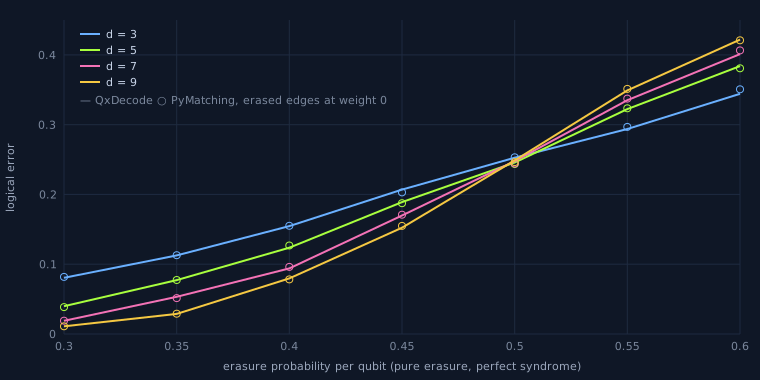
With bit flips on the other qubits the crossing falls as the erased share grows — near 8–10 % of flips without erasure, about 8 % with 10 % erasure, about 6 % with 20 % — in line with the usual linear trade-off; QxDecode is a little less accurate than matching without erasure (as union-find is) and close to it once erasures dominate:
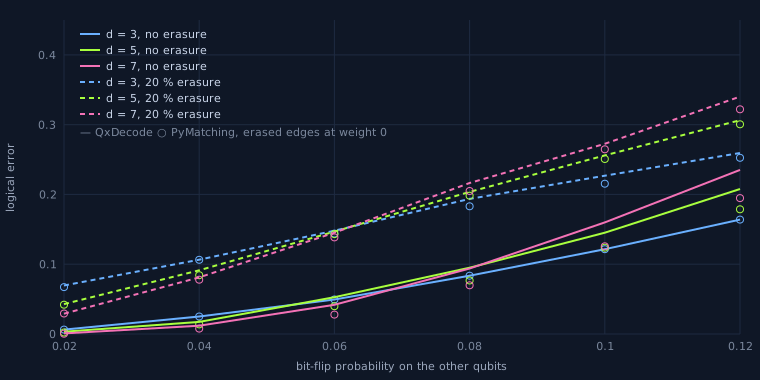
At circuit level, QxStab samples heralded erasure (Stim's HERALDED_ERASE semantics; on a d = 3 memory with 2 % erasure its 51 detectors and 27 heralds agree with Stim's sampler, exact tests, smallest corrected p 0.89). Surface-code memories, d rounds, Pauli noise 0.1 % on every operation and heralded erasure on every data qubit each round; the decoding graph from Stim's error model, each herald mapped to the edges its erasure can flip; 20,000 shots a point:
| d | erasure per round | QxDecode, with heralds | PyMatching, with heralds | PyMatching, ignoring them |
|---|---|---|---|---|
| 3 | 0 % | 0.06 % | 0.05 % | 0.05 % |
| 3 | 2 % | 0.29 % | 0.29 % | 1.31 % |
| 3 | 4 % | 0.66 % | 0.64 % | 2.99 % |
| 3 | 8 % | 1.51 % | 1.49 % | 8.48 % |
| 5 | 0 % | 0.01 % | 0.01 % | 0.01 % |
| 5 | 2 % | 0.03 % | 0.06 % | 0.65 % |
| 5 | 4 % | 0.12 % | 0.10 % | 2.70 % |
| 5 | 8 % | 0.47 % | 0.41 % | 9.96 % |
| 7 | 0 % | 0.00 % | 0.00 % | 0.00 % |
| 7 | 2 % | 0.03 % | 0.03 % | 0.34 % |
| 7 | 4 % | 0.04 % | 0.03 % | 1.82 % |
| 7 | 8 % | 0.14 % | 0.14 % | 10.43 % |
Knowing where the losses were is worth about twenty times in logical error at d = 5 and 4 % erasure, and keeps larger codes better even at 8 % per round — where, without the heralds, the larger code is already worse. QxDecode uses the heralds about as well as matching does (data, pure-erasure data, mixed data, tools/erasure/).
The 2.7 % loss figure. Romero and Milburn's review (p. 27) says fusion-based computation "can tolerate a 2.7 % probability of suffering a single-photon loss". It comes from Bartolucci et al. (Nat. Commun. 14, 912, 2023, Sec. VI and Appendix B): the 6-ring fusion network with (2,2)-Shor-encoded resource states and fusions boosted with a Bell pair (failure 1/4, four photons per fusion). We reproduce it from their formulas — 2.71 % per photon, which is 10.4 % that at least one of the four photons is lost, and their 43.2 % failure threshold at zero loss — taking their simulated erasure threshold (11.98 %) as given; we have not simulated the fusion network itself. Unencoded, the same network tolerates no loss at failure 1/4; the 4-star network, encoded, about 1.0 % (tools/optics/fbqc_loss.py).
One mode: GKP and cat qubits (Gottesman, Kitaev, Preskill, PRA 64, 012310, 2001; Ralph et al., PRA 68, 042319, 2003). A third simulator, for one optical mode in continuous variables, again written twice: cv.py in Python works in the Fock basis and on a grid in q, QxCV in Elixir on the grid alone, its p side summed analytically over the peaks instead of by FFT. Squeezed vacuum from the Fock basis matches the closed-form wavefunction to 8 × 10⁻¹⁵, and Eq. 24 holds to 9 × 10⁻¹⁴. Eq. 26 holds only if the phases of Eqs. 22 and 25 agree: with ζ = re^(−2iϕ) as printed, the rotation must be e^(+iϕ), not Eq. 25's e^(−iϕ) (flipping either sign works); as printed, the variances are off by up to 5.6 when ϕ ≠ 0.
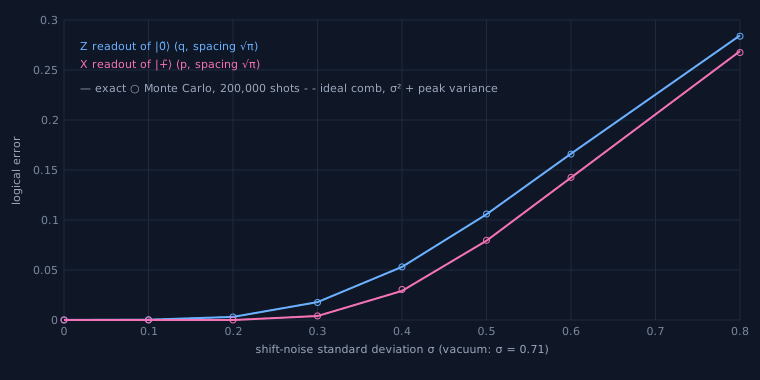
GKP states (Eq. 38; α = √π, peaks squeezed 10 dB, Δ² = 0.01). The logical Z̄ = e^(iπq/α) reads ±0.924 on |0̃⟩ and |1̃⟩, equal to an analytic sum over the Gaussian peaks to 10⁻¹⁰; X̄ = e^(−ipα) takes |0̃⟩ to |1̃⟩ with fidelity 0.984 — the envelope does not move with the peaks — also as predicted. Read out after a Gaussian shift of σ, the logical error from the exact integral, from 200,000 sampled readouts, and from the closed form for an ideal comb with σ² plus the peak's variance agree (the closed form to 1.5 × 10⁻⁷), in q and in p. Eq. 39's bounds show as an error of ½ (to 2 × 10⁻⁵) at a shift of α/2 in q or π/2α in p. QxCV's X readout (the Fourier sum) and Python's (the FFT) agree to 10⁻¹³:
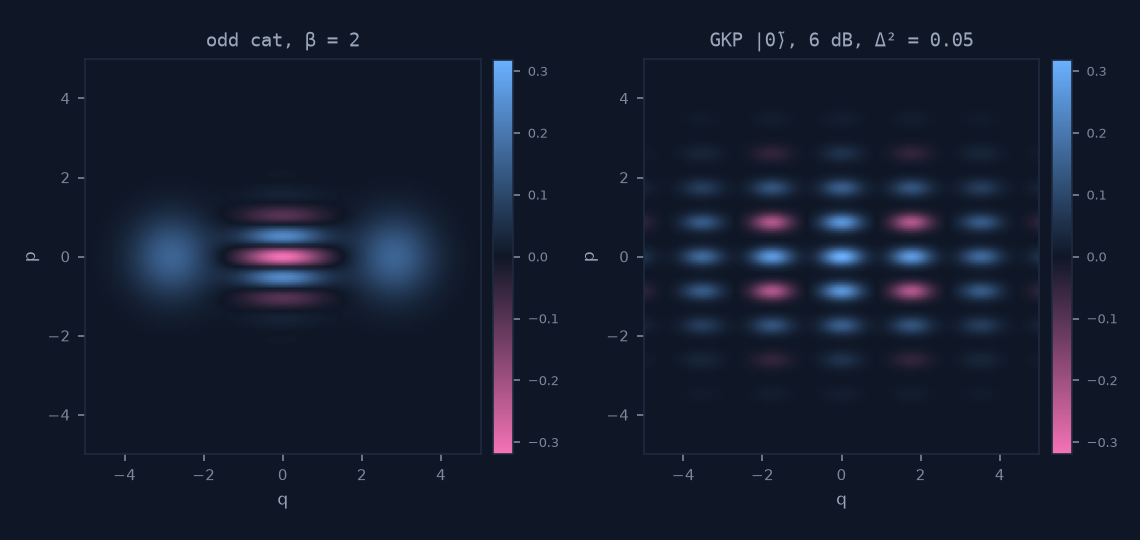
The review's Fig. 5, read from the vector curve in its PDF. The peaks sit at multiples of √π, as Eq. 38 gives with α = √π; each peak's variance fits 0.11 — near e^(−2r) = 0.09 for r = 1.2, while the caption says e^(2r) = 11; and the |1̃⟩ envelope falls off four times faster than the |0̃⟩ one (4.00), which a single Δ in Eq. 38 cannot give. With the caption's Δ̃ = 0.01, amplitudes e^(−Δ̃(sα)²) for |0̃⟩ and e^(−Δ̃[(2s+1)α]²) for |1̃⟩ fit both panels: the |0̃⟩ panel looks drawn with s where Eq. 38 has 2s.

Cat states (Eq. 75). From the Fock basis and from the grid they agree to 10⁻¹⁵; they hold only even or only odd photon numbers, and the Wigner function at the origin is ⟨Π⟩/π = ±1/π (to 2 × 10⁻¹⁶). Eq. 40's N±⁻¹ leaves the state with norm² 1/N±; Eq. 75's N±^(−1/2) is right. Photon loss is the cat code's error — one lost photon flips the parity — and after a loss 1 − η, ⟨Π⟩ = cosh(β²(1 − 2η))/cosh β² for the even cat (sinh for the odd): the generating function (QxCV) and the Fock amplitudes thinned photon by photon (Python) agree to 2 × 10⁻¹⁶.
A comb heralded by homodyne detection (Eqs. 66–73). With Eq. 69's Kraus amplitude the outcomes y sum to one for every q (to 10⁻⁹); Eq. 70 as printed sums to 1/√2 — it lacks the ½ in the exponent. A phase-squeezed input with the outcome y = 0 gives peaks every π/θ (√π here: a GKP-like comb); other outcomes give pairs, with gaps 2 arccos(y/2β)/θ and the rest of the period, as sampled:
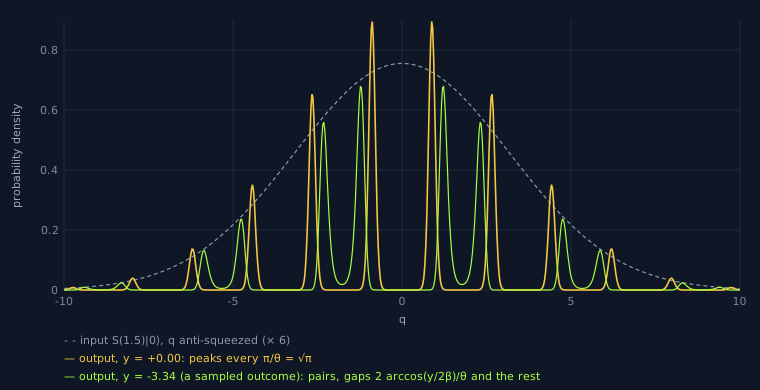
checks · Elixir against Python · readout · Eq. 39 shifts · Fig. 5 as read · comb · tools/optics/cv_checks.py, xcheck_cv.py · /quantum/optics/gkp, /cat, /comb
From the review we started from (Romero and Milburn, arXiv:2404.03367): its Fig. 8 gives the third angle as +22.5°, which does not make an NS gate — only the text's −22.5° reproduces KLM's unitary; we also found slips in its Eqs. 13, 22, 40 and 70, a sign between Eqs. 22 and 25, its growth arithmetic, its Fig. 5 (caption and envelopes) and its Fig. 10 (above), listed in the repository's NOTES.md. Every number here comes from the primary paper or our own derivation.
HOM data · KLM checks · against Perceval · tools/optics/ · /quantum/optics/hom?gt=1, /quantum/optics/ns, /quantum/optics/cz?input=11&shots=10000
Question. Under concurrent load, does a union-find decoder on the BEAM — every syndrome its own lightweight process, many decoded at once on all cores — keep its tail latency bounded, at a throughput near a compiled decoder's?
Baselines, to separate the algorithm from the language. Union-find in a compiled language (Rust or C++), and in plain Python; and PyMatching 2.4 (minimum-weight matching, C++) — each run under the same load as ours: a worker pool on the same cores, fed from a queue, with 1, 100 and 10,000 syndromes in flight. Same machine, same syndromes (sampled by QxStab and by Stim from the threshold-study circuits, d = 3 to 9, p = 0.1 to 1 %). The decoding graph comes from Stim's detector error model for every decoder, ours included: there our work depends on Stim.
The deadline, and why the BEAM. The BEAM is soft real-time: it will not decode for superconducting hardware, whose rounds take about a microsecond. Trapped-ion and neutral-atom machines run rounds of a millisecond or more, and the software that orchestrates any machine works in milliseconds; we test against a 1 ms deadline at d = 5. The question is whether preemptive per-process scheduling keeps the tail there when the queue grows, where a single-threaded decoder's queue waits pile up.
Hypothesis, and what falsifies it. At d = 5: our 99th-percentile latency stays under 1 ms with 10,000 syndromes in flight, growing no more than 2× from 1 to 10,000; and our throughput per core is within 2× of compiled union-find. Either number missing falsifies it. We expect to lose against PyMatching, which decodes such syndromes in microseconds, and we report by how much — and the logical error rate, since union-find is a little less accurate than matching. A partial result still says something: bounded latency at a lower throughput would describe what the BEAM is for.
Protocol. One warm-up pass; 10 repeated runs per point, medians with 95 % intervals by bootstrap; garbage collection left on and reported (BEAM processes collect their own heaps; we record the time spent); scripts, raw timings and syndromes published with the results.
QxDecode (lib/qx_decode.ex): union-find after Delfosse and Nickerson, weighted (edge lengths from the error probabilities, in quarter steps of the lightest edge), peeled over a minimum-weight spanning tree of each cluster. Its first version peeled over a breadth-first tree and failed a simple pattern — two detectors next to each other and the boundary — ten times too often at low noise; comparing with PyMatching shot by shot found it. On the same 100,000 syndromes per point, both on Stim's detector error model:
| d | p | ours | PyMatching | ratio | µs/syndrome, ours, 1 process | µs, PyMatching, 1 core | ours, 20 cores, /s | PyMatching, 1 core, /s |
|---|---|---|---|---|---|---|---|---|
| 3 | 0.1 % | 0.095 % | 0.083 % | 1.145× | 1.6 | 0.04 | 7,001k | 24,748k |
| 3 | 0.4 % | 1.30 % | 1.23 % | 1.057× | 4.5 | 0.11 | 3,800k | 9,407k |
| 3 | 0.6 % | 3.46 % | 2.52 % | 1.372× | 3.1 | 0.16 | 2,637k | 6,415k |
| 3 | 0.8 % | 4.85 % | 4.18 % | 1.161× | 4.3 | 0.21 | 2,004k | 4,716k |
| 5 | 0.1 % | 0.022 % | 0.020 % | 1.1× | 5.0 | 0.33 | 1,779k | 3,076k |
| 5 | 0.4 % | 0.830 % | 0.731 % | 1.135× | 21.5 | 1.01 | 537k | 994k |
| 5 | 0.6 % | 2.83 % | 2.36 % | 1.198× | 34.5 | 1.65 | 367k | 607k |
| 5 | 0.8 % | 6.08 % | 5.04 % | 1.205× | 47.9 | 2.36 | 244k | 424k |
| 7 | 0.1 % | 0.001 % | 0.002 % | 0.5× | 17.2 | 1.23 | 625k | 815k |
| 7 | 0.4 % | 0.528 % | 0.429 % | 1.231× | 83.0 | 4.08 | 152k | 245k |
| 7 | 0.6 % | 2.36 % | 1.93 % | 1.218× | 134.1 | 6.51 | 88k | 154k |
| 7 | 0.8 % | 6.48 % | 5.25 % | 1.234× | 440.2 | 8.82 | 61k | 113k |
What this says. Accuracy: our logical error rate is 1.06 to 1.37 times PyMatching's where both have enough failures to tell — union-find's usual distance from matching; McNemar's exact test on the shots where they disagree finds the difference real at most points. Speed: per syndrome on one core we are 14 to 50 times slower than PyMatching; on all 20 cores our throughput is about one PyMatching core. That is the throughput half of the hypothesis already answered for PyMatching (we lose, as expected); the comparison against compiled union-find and the latency under load follow below (data, tools/dem_graph.py, tools/decode_runs.exs, tools/decoder_compare.py).
First, our design had a flaw. With a fixed number of syndromes in flight, Little's law makes the mean latency that number divided by the throughput: 10,000 in flight at 1 ms needs 10 million syndromes a second from any decoder. That measures throughput, not scheduling. We kept the closed-loop runs, and added the usual test: syndromes arriving at random (Poisson) at 50, 80 and 95 % of what each decoder sustains through its own harness, and the latency from arrival to answer.
The setup. The same 8 fast cores (of a 20-core Arm machine that also runs other services) for every decoder; the same graph and syndromes at p = 0.4 %. QxDecode on 8 BEAM schedulers, one process per syndrome, released by a dispatcher that spins on the clock; union-find in C++ (tools/load/uf.cpp, the same algorithm: identical predictions on 99.94–100 % of shots), a spinning dispatcher and 7 worker threads; PyMatching and union-find in Python, a dispatcher and 7 worker processes. Each harness also ran with a decoder that does nothing, to show its own cost. 10 seeds at d = 5, 3 at d = 3 and 7; medians.
| d | decoder | decode only, /s | through harness, /s | p99 at 50 % | at 80 % | at 95 % | over 1 ms at 50 % | no-op p99 at 50 % |
|---|---|---|---|---|---|---|---|---|
| 3 | QxDecode, BEAM | 2,588k | 505k | 4.29 ms | 6.23 ms | 7.74 ms | 2.4 % | 2.41 ms |
| 3 | union-find, C++ | 15,900k | 4,622k | 310 µs | 2 µs | 2 µs | 0.0 % | 1 µs |
| 5 | QxDecode, BEAM | 331k | 184k | 1.24 ms | 13.57 ms | 8.53 ms | 1.2 % | 45 µs |
| 5 | union-find, C++ | 3,940k | 3,671k | 1.58 ms | 1.49 ms | 1.98 ms | 2.8 % | 1 µs |
| 7 | QxDecode, BEAM | 92k | 59k | 751 µs | 3.07 ms | 25.40 ms | 0.6 % | 36 µs |
| 7 | union-find, C++ | 1,358k | 1,329k | 14 µs | 20 µs | 108 µs | 0.0 % | 1 µs |
Against the hypothesis, at d = 5. Throughput within 2× of compiled union-find: no — 12 times less decoding alone, 20 times less through the harness. 99th percentile under 1 ms: at half load 1.24 ms (95 % interval 894 µs–1.73 ms), at 80 % 13.57 ms, at 95 % 8.53 ms. Growth bounded: no. The hypothesis is falsified.
What it does show. A process per syndrome costs the BEAM more than the decoding: its harness alone, with no decoding, has a 99th percentile of 2.41 ms at half load for d = 3 — spawning and messaging at a few hundred thousand a second is the bottleneck, not the scheduler's fairness. C++'s tails are bimodal across seeds — microseconds in some runs, milliseconds in others — which fits interference from the machine's other work on shared cores; a clean tail measurement needs a machine to itself. Python's harness costs more than any deadline here (its no-op p99 is tens of milliseconds), so for PyMatching and Python union-find only throughput is meaningful: about 124k and 93k syndromes a second through it at d = 5.
Next. Decode many syndromes per process (batches) rather than one each, to separate the BEAM's scheduling from its spawning cost; a dedicated machine for the tails; then the question again. Data: summary, every run; tools/load/.
A register of n qubits is described by 2n complex amplitudes. A measurement returns one outcome, with probability given by its amplitude squared; the amplitudes themselves are never read out. Speedups come from interference: an algorithm arranges the amplitudes so that wrong answers cancel and right ones reinforce before that one measurement.
|ψ⟩ = α|0⟩ + β|1⟩, |α|² + |β|² = 1
Quantum circuit simulation on QxSim, written in Elixir and running on the Erlang virtual machine: four algorithms and protocols, one quantum ML circuit, five error-correcting codes. The charts below are not pictures: each card ran its circuit when this section came into view, and draws the outcomes it measured, shot by shot. Run any of them again, or open the full demo page for the circuits in OpenQASM and the error-correction details.
Two qubits, maximally entangled: only 00 and 11 appear, half each.
A random state sent from Alice to Bob through a Bell pair and two classical bits; Bob corrects it, then undoes its preparation: his qubit (leftmost) must read 0 every time.
A random marked state among N = 2ⁿ. Line: its probability after each iteration, exact; dots: theory sin²((2k+1)θ). The optimum is near (π/4)√N.
Rx rotations and an entangling CNOT layer — the shape of a quantum ML model.
Compiled for a = 7: 7⁴ ≡ 1 (mod 15), so the period is built into the circuit — it shows the structure, not a speedup. k = 2, 6 give 3 × 5 directly; k = 4 after a check; k = 0 nothing.
N = 15 or 21, any a: 2n counting qubits, the inverse QFT, continued fractions; nothing about the period goes in. The multiplication by a^(2^j) mod N is a permutation computed classically (an oracle, not a gate circuit). Failing choices of a fail, and say why.
Logical |0⟩ on three qubits, an X error on qubit 1; two ancillas measure the parities, a majority vote of the readout corrects it. Noiseless gates.
Logical |0⟩ as |+++⟩, a Z error on qubit 1; checks X₀X₁ and X₁X₂ on one reused ancilla find it, a Z corrects it. Read out in the X basis.
A Y error (bit and phase flip) on qubit 1; six Z checks and two X checks find both, the decoder corrects both. Bars: the logical qubit, 0 or 1.
A Y error on qubit 1; three Z and three X checks give its position twice, in binary; X and Z correct it. Bars: the logical qubit, 0 or 1.
The full distance-3 code: nine data qubits, all eight stabilizers on one reused ancilla, a Y error on qubit 1; a lookup decoder corrects both flips. Bars: the logical qubit.
curl "https://quanterall.com/quantum/bell?shots=1024&seed=42"
curl "https://quanterall.com/quantum/shor15?shots=1024&seed=42"
curl "https://quanterall.com/quantum/qec/steane7?shots=1024&error_qubit=3&seed=42"
curl "https://quanterall.com/quantum/entangle?shots=2000"
curl "https://quanterall.com/quantum/migrate?shots=100"
Every card is one such call: the path is the demo's name (bell, teleport, grover, qml, shor15, qec/…), the answer is JSON with the counts and the circuit in OpenQASM. Add seed (0 to 2³²−1) and the same call gives the same counts; without one, the answer reports the seed it drew, so any run can be repeated. The process models run many processes of their own and are not seeded. Limits: up to 10,000 shots a call, 5 calls a second per visitor (bursts of 20), 4 simulations at once. About the code: the demos began on qx, Craig Richards' Elixir quantum simulator (Apache-2.0; we used version 0.5.1), and we credit it. The simulators now running are separate code, and the comparison is published (tools/qx_compare.py, result): every qx release depends on Nx, our service does not depend on qx; none of 19 distinctive names of ours occurs in qx's 207 commits; and cut into 8-token sequences (comments and strings removed), at most 2 % of any of our files occurs in any qx release — while consecutive qx releases share 92 to 100 %, so the measure does find shared code where there is some. It measures textual copying only, not the same design written again in other words. Earlier labels here that read "qx_sim 0.5.1" named the starting point, not the code that runs.
Two quantum concepts modelled with what the Erlang virtual machine does best — isolated processes and nodes — for teaching and for demonstrating the concepts. Both run live below, on real BEAM processes; the numbers are measured, not drawn.
Each round spawns three processes: a pair process holding the shared state |Φ⁺⟩, and Alice and Bob. They never message each other; each asks the pair to measure its own qubit at an angle. Whoever asks first collapses the shared state, and the other reads a correlated result. A classical simulation: the pair process is a central state holder, so this shows the statistics of entanglement, not nonlocality.
A crystal makes the photon pair; neither photon has a polarization of its own until one meets a polarizer. A polarizer turns half as much as the qubit's measurement axis, so the settings are 0° or 45° for Alice and 22.5° or 67.5° for Bob, as in the Bell tests of Aspect (1982) and Weihs (1998). Played: this run's first 24 pairs.
Node A is this server's BEAM; node B is a second BEAM node, a separate operating-system process. Alice's process holds a qubit ψ, measures it against her half of a Bell pair and ends; only two classical bits go to node B, where a new process applies the correction and holds the same state. ψ is unknown to the protocol but known to the simulator, which checks the result: this shows the protocol's structure, not a physical transmission.
As in the first teleportation experiment (Bouwmeester et al., Innsbruck 1997) and from the ground to the Micius satellite over 1,400 km (2017): |0⟩ is horizontal and |1⟩ vertical polarization, ψ is drawn as its polarization ellipse. A Bell-state analyser built only from beam splitters tells apart two of the four outcomes; the model, like trapped-ion experiments, uses all four.
We propose thesis topics and seminars around our circuit simulator — a decoder, a noise model, the full Shor circuit — for students at Varna Free University, and joint work through IAPS and New Bulgarian University where it fits. Students who take part are credited here. To propose or take a topic: [email protected].
Write to [email protected] — for research collaboration, to join, or to work with us. Or through the code: open an issue or a pull request on GitHub; or on LinkedIn.
Quanterall Ltd. is a private company, separate from the Institute for Advanced Physical Studies and from the universities named here. Their names say where our people work and teach; they do not endorse this site.
The twenty-three years behind this move are distributed and fault-tolerant software, not quantum physics. They carry over in specific places — concurrency, fault-injection testing, simulation — and not in others. What we lack is quantum-specific depth; we are building it in the open, on this page.